Getting real GPU acceleration for Stable Diffusion on an unsupported AMD Radeon 780M
My NucBox K8 Plus mini PC runs a Ryzen APU with a Radeon 780M built in, gfx1103 in AMD’s internal naming. It’s a common chip, the kind of integrated GPU sitting inside plenty of laptops and mini PCs sold today. AMD’s own ROCm builds skip it anyway: the compiled rocBLAS and MIOpen kernels for gfx1103 simply aren’t in AMD’s official binaries. I wanted ComfyUI running Stable Diffusion on the GPU itself.
DirectML: fast until it isn’t
DirectML is the default path Windows offers for AMD GPUs in ComfyUI: install torch-directml, skip the exotic driver setup. I hit a UnicodeDecodeError right away, before a single image generated. The cause was buried in a native string decode inside DirectML, and it choked on my Windows locale, Japanese Shift-JIS. Switching the system locale to English with UTF-8 cleared it.
Small jobs worked after that. Anything past roughly eight sampling steps at 512x512 crashed the driver outright, “GPU will not respond to more commands,” or ran out of memory. I tested this across several prompts and step counts; the ceiling held every time. ComfyUI’s own startup warning says as much: torch-directml is barely maintained. It earns its keep for a quick preview, but the crash ceiling ruled out real generations.
ZLUDA: the bigger swing
ZLUDA intercepts CUDA calls at the DLL level and translates them to AMD’s ROCm/HIP stack, so an off-the-shelf CUDA build of PyTorch runs on AMD hardware without a special build. Community developers had already compiled rocBLAS kernels specifically for gfx1103, filling the gap AMD left, and I’d seen reports of similar-generation APUs, the RX 8600G class, getting real speedups this way.
Getting it running meant the AMD HIP SDK, patched rocBLAS and hipBLASLt libraries dropped into the SDK’s bin folder, a ZLUDA-enhanced ComfyUI fork called ComfyUI-Zluda, and a separate model directory wired up through extra_model_paths.yaml.
The bug gauntlet
Eight separate failures stood between that setup and a working generation. None of them shared a root cause.
-
Scripts silently “not recognized.”
install-n.batand even bare test scripts refused to run, with no real error. Windows’NoDefaultCurrentDirectoryInExePathhardening blocks execution of a bare filename from the current directory. Prefixing every call with.\fixed it. -
ZLUDA’s injected
nccl.dllkept disappearing. ZLUDA replaces this DLL to redirect NCCL calls, and Windows Defender was quietly deleting it as a real-time threat. A Defender exclusion for the ComfyUI folder stopped the deletions. -
Crashes continued anyway. A separate, stricter layer called Smart App Control was blocking the same injected binaries independently of regular Defender, and it never showed up in the usual quarantine log. Turning it off fixed the crashes. It’s a one-way switch: turning it back on later needs a clean Windows reinstall, a real cost worth weighing first.
-
Environment variables vanished between shell sessions.
HIP_PATHand the SDK’sPATHentry were set in one shell, then gone in the next. Nothing was broken; variables set in a running process don’t carry over to a fresh shell. Setting them at the system level made them stick for good. -
A numpy/scipy version mismatch baked into the installer. The setup script’s own comment called its numpy pin a temporary fix, and it no longer matched what the installed scipy needed. Upgrading numpy to the version scipy wanted resolved it.
-
A hard access-violation crash in
torch.nn.functional.linear. Reproducible every time, in fp16 and fp32 alike. The rocBLAS and Tensile kernel binaries shipped with HIP SDK 6.2.4 turned out to be the problem. Switching to HIP SDK 6.4.2, with its own separately compiled kernels, made the crash disappear. -
MIOpen convolutions failing with “unable to find an engine.” gfx1103 has no precompiled MIOpen kernel database at all, another gap AMD left in its own tooling. Disabling cuDNN and MIOpen globally forced PyTorch onto its native convolution path, and generation kept working.
-
A leftover custom node crashing VAEDecode. The project’s own cuDNN-toggle helper node broke once cuDNN was already off globally. It was redundant at that point, so I removed it.
Results
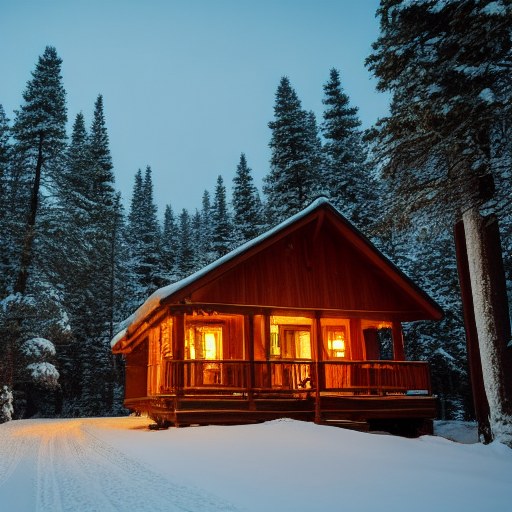
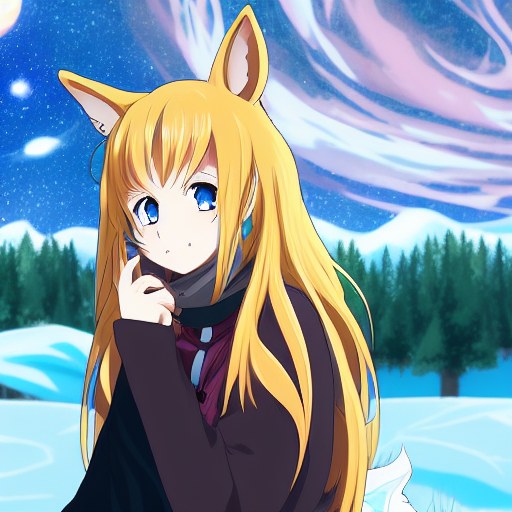
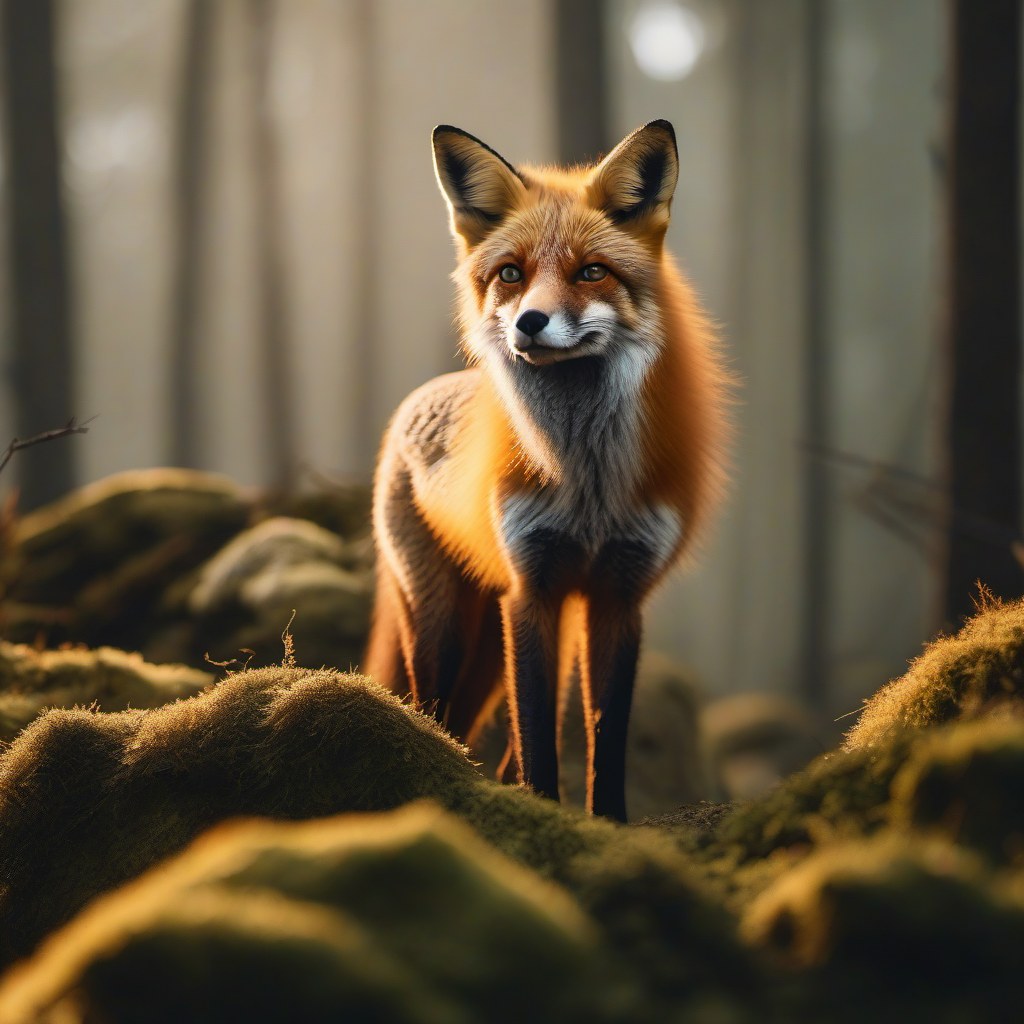
Generation used to mean the CPU alone, at roughly five seconds a step, or DirectML’s short window before it crashed. With all eight fixes in place, ZLUDA holds up across model sizes and resolutions:
| Test | Model | Resolution | Time | Speed |
|---|---|---|---|---|
| Cabin | SD 1.5 | 512x512 | 20.7s | ~1.46 it/s |
| Anime fox-girl | SD 1.5 | 512x512 | 20.0s | ~1.46 it/s |
| Red fox photo | SDXL | 1024x1024 | 98.4s | ~4.1s/it |
The SDXL run costs more per step at four times the pixel count, which is expected. The iteration speed itself stayed consistent across all three.
If you’re on this exact GPU
If an exact error string brought you here, two open GitHub issues are worth reading directly: rocBLAS’s TensileLibrary missing gfx1103, and MIOpen’s precompiled convolution database missing it too. Both confirm this isn’t a local misconfiguration.
Smart App Control has to go off for ZLUDA’s injected binaries to survive. It’s worth knowing before you commit to this path, since reversing it means reinstalling Windows.
Every binary in this setup, from the rocBLAS patches to the ZLUDA fork to the HIP SDK version pairing, comes from community work outside AMD’s official support. It held up fine for a personal machine running local generations. I wouldn’t put it anywhere near a production box.
(Update: AMD’s own tooling has since caught up enough to retire this whole setup. See the write-up on switching to AMD’s TheRock. The same chip later ran a 20B-class image model at a very different pace: see the Qwen-Image-2512 write-up.)